
Expose an agent to other agents
So far Plexus fronted your files and tools. But a running coding agent is itself a capability. Machine A can expose its Claude Code execution entry point — claudecode.run — through Plexus, and an agent on machine B can call it. That flips the usual picture: instead of one agent reaching many resources, one orchestrator reaches many workers, and each worker sits behind its own owner's gate. On macOS claudecode.run is a first-party source that registers itself — nothing to configure. Expose it, and other agents can put your machine to work coding, one approved run at a time.
Why execution is the highest-stakes call
Reads can stand. A folder read is low-risk and you pre-decided it, so it flows without interrupting you. Execution is per-use by default. An execute capability is approved per use, every time — and the agent can never lift that itself. The only way an execute grant stands is your own deliberate opt-in at connect time, for one specific agent + capability (off by default, double-confirmed). Handing another agent the ability to run code on your machine is the sharpest edge Plexus governs, so the gate stays in front of every single call.
You can see the whole rule in the approval card:
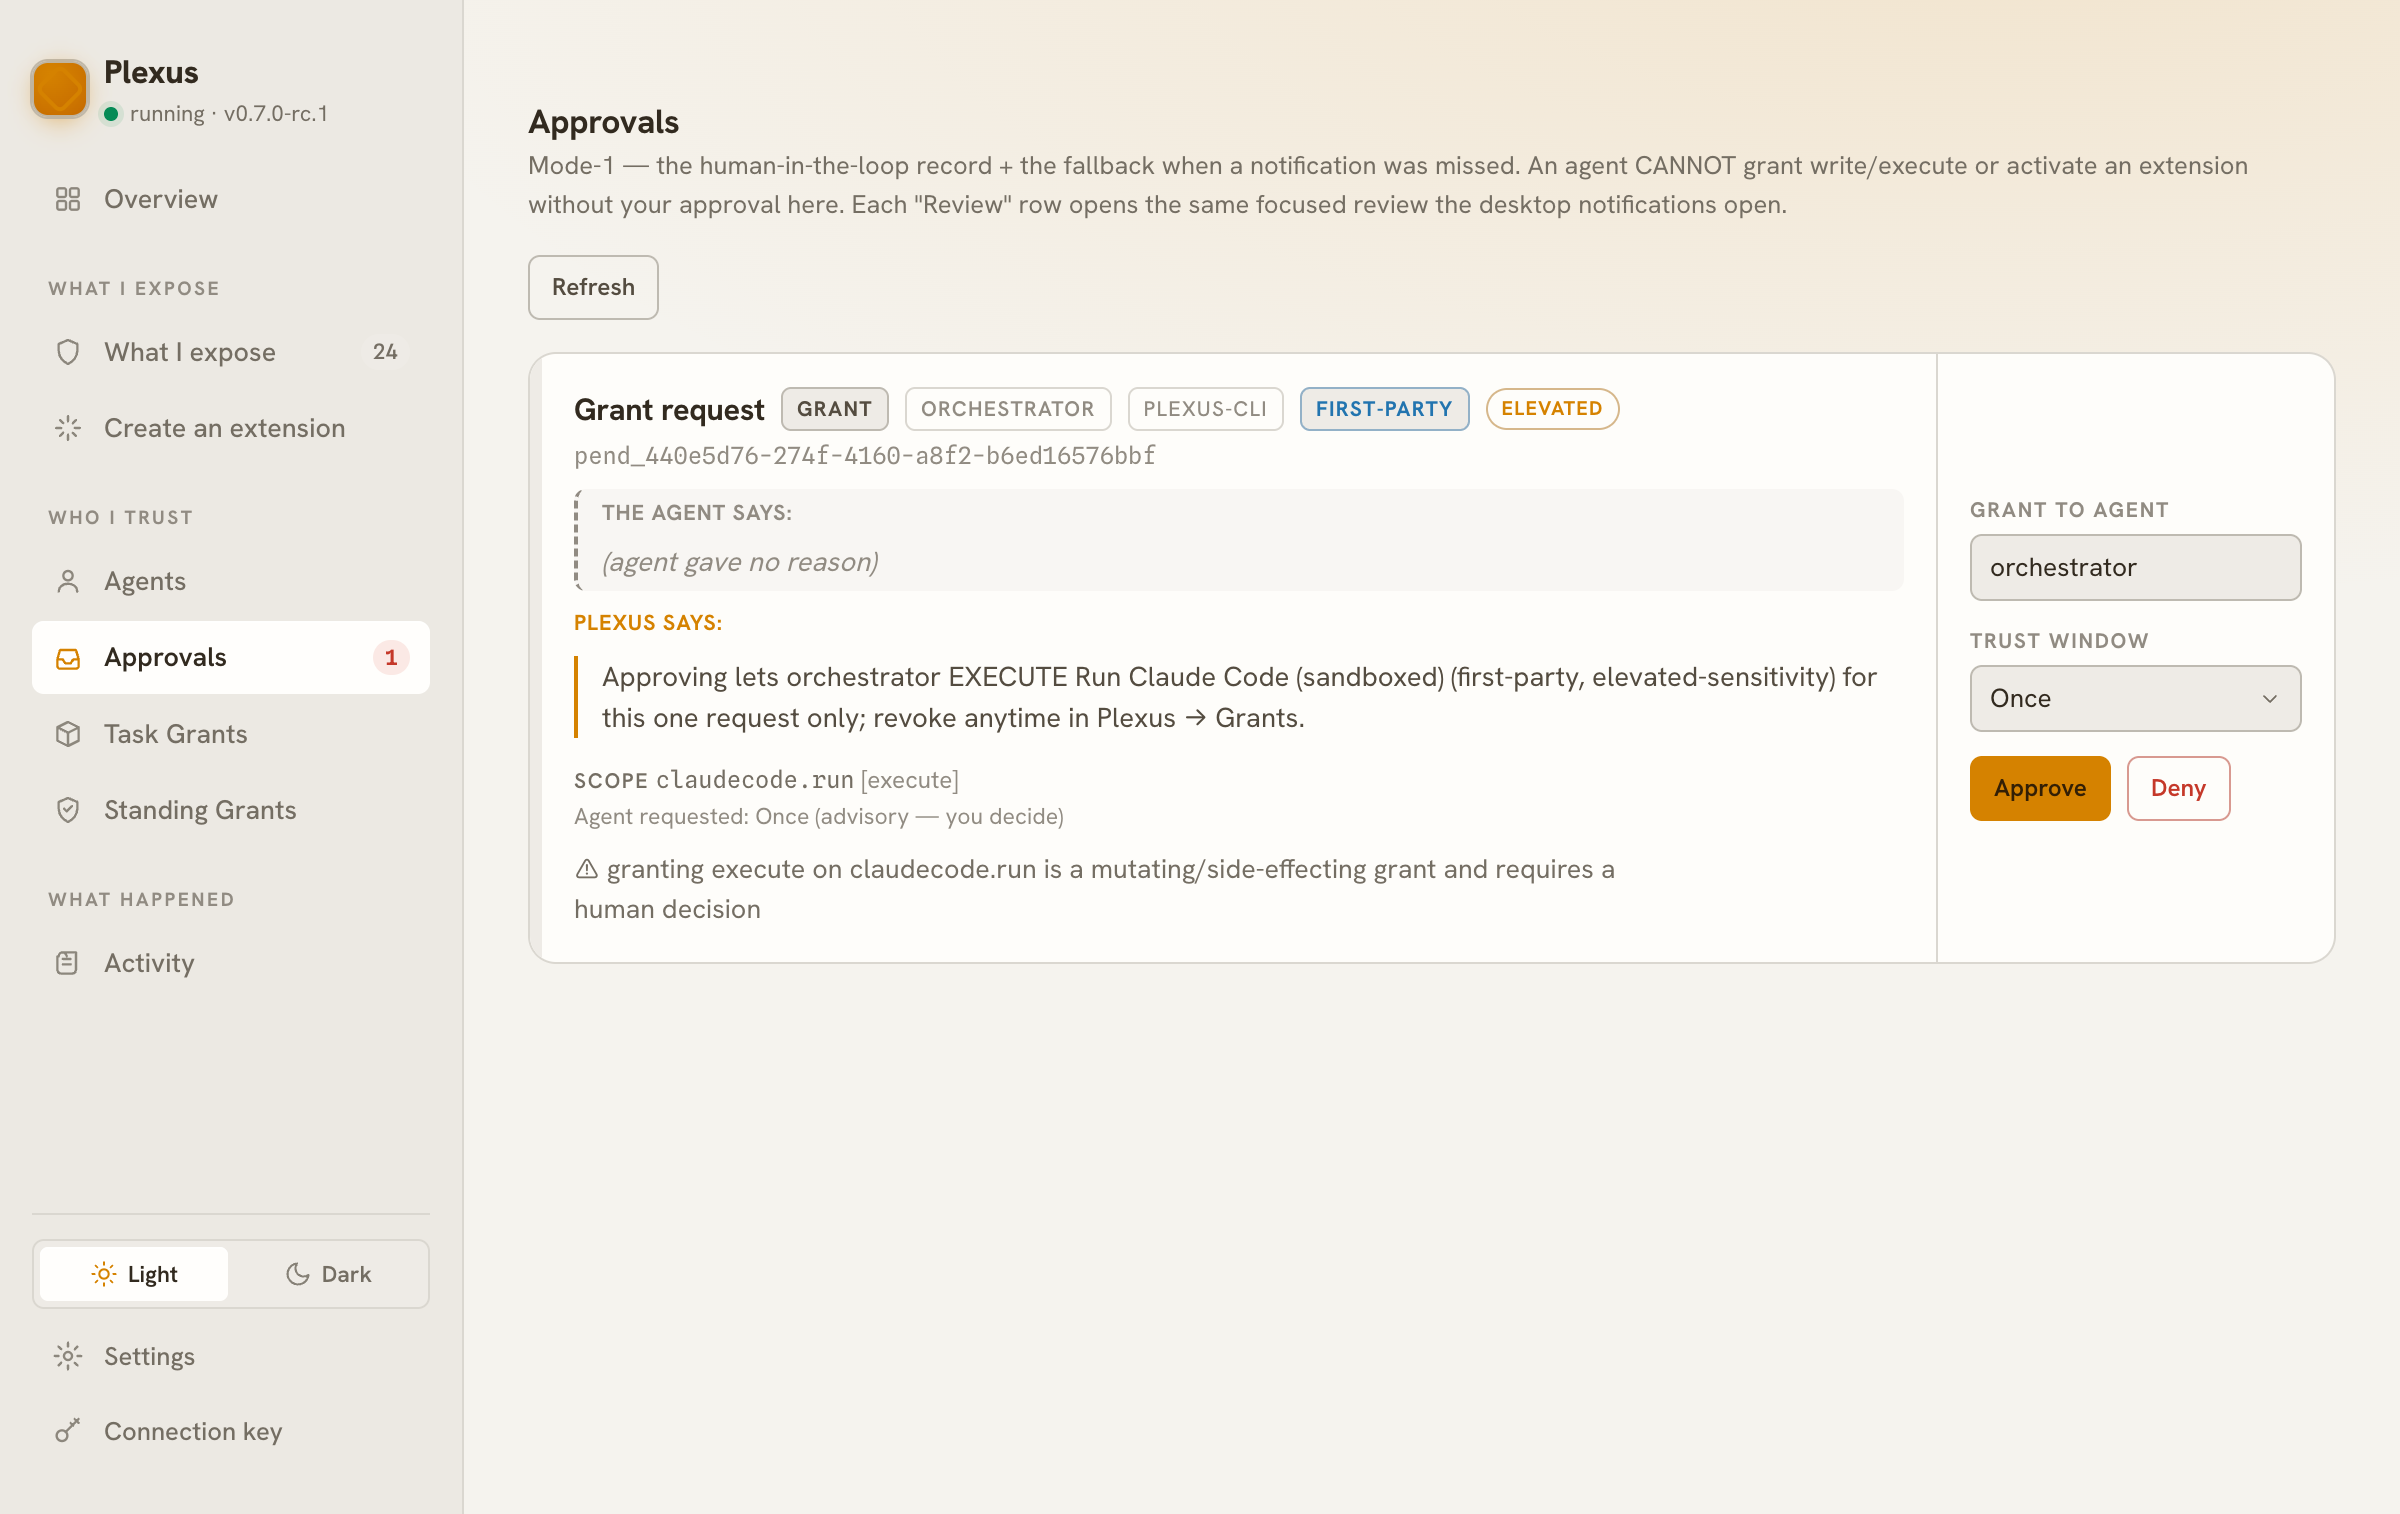
Two things on this card don't appear on a read approval. The ELEVATED badge and the mutating/side-effecting warning mark it as a human-decision-required act. And the trust window resolves to Once: the dropdown shows the usual window choices, but for an execute capability you did not opt into standing at connect, the gateway clamps whatever you pick to Once — the rule lives in the grant service, not the UI. Approve this call and you've authorized exactly this call — the next one pends again.
What one call looks like
The caller discovers its surface with list, exactly as in the trust loop. The execute capability shows up as needs-approval — it isn't pre-granted by default:
  ○ claudecode.run — Run Claude Code (execute)  [first-party, elevated]
      Launch headless Claude Code to do REAL coding work ... in ONE authorized directory. By
      default the run is kernel-jailed to that directory: its reads, writes and temp files live
      there ... The result's `isolation` field states which policy the run had ... you only pass
      a `{ prompt }` ... otherwise the call PENDS and you wait for the owner's decision ...
The call itself pends every time, resolves when the owner approves, and returns:
$ plexus-orchestrator claudecode.run --input '{"prompt":"Read README.md, then add a small greet(name) example ..."}'
plexus: 'claudecode.run' is awaiting the owner's approval — waiting (up to 15 min). Approve it in the Plexus console.
# (owner approves — trust window resolves to "Once"; this execute wasn't opted into standing)
plexus: approved — invoking 'claudecode.run'.
{
  "ok": true,
  "launched": false,
  "isolation": {
    "policy": "jail",
    "scope": { "files": "authorized-dir", "temp": "authorized-dir", "network": "open", "toolState": "own-config-read-only" },
    "enforced": false
  },
  "output": "",
  "exitCode": null,
  "reason": "record mode: the owner has not enabled real launch for this source (Plexus console → What I expose → Claude Code → Real launch), so the launch command was assembled and audited but not spawned",
  "op": "run"
}
Note launched: false. Out of the box claudecode.run runs in record mode: the launch command is fully assembled and audited, but the Claude Code process is not spawned — so the call burns no model credit. What's real in record mode is everything that matters for trust: the enrollment, the per-use pend, the owner's decision, and the confinement posture (isolation.policy: "jail", Plexus's own kernel jail around the authorized directory; enforced stays false until a real run is verified and launched inside it). You can walk the entire authorization loop and never spend a token. Flipping to a real run is a deliberate, separate switch — see Real launch.
What the owner sees vs. what the agent sees
The JSON above is the agent's whole view. It's deliberately thin: ok / launched / isolation / output / exitCode / reason, and nothing else. isolation says what the run could reach in path-free words. The agent never learns the absolute jail path, the machine's layout, or the full argv — handing those over would let a caller fingerprint the owner's machine. Reachability buys an agent a result, never a map.
The owner's audit keeps the full posture:
invoke claudecode.run detail = {
  transport: "in-process", kind: "capability", op: "run",
  policy: "jail",
  jail: "<the authorized dir>",
  mechanism: "sandbox-exec",
  launched: false,
  isolation: { policy: "jail", mechanism: "sandbox-exec", scope: {...}, enforced: false },
  argv: ["/usr/bin/sandbox-exec","-f","<cc-confine.sb>","-D","JAIL=<root>","-D","HOMEDIR=…",
         "-D","TOOL_HOME=…","-D","TOOL_BIN_DIR=…","-D","TOOL_PKG_DIR=…","-D","TOOL_INTERP_DIR=…",
         "<claude>","-p","«prompt»","--dangerously-skip-permissions","--permission-mode","bypassPermissions",
         "--settings","{\"sandbox\":{\"enabled\":false}}"],   # prompt is masked to «prompt» in the audit argv
  confinement: {...}   # root, jail, homedir, toolHome, profile, binaryDirs; plus the canary on a real launch
}
Same call, two projections. The agent gets the minimal result it needs to act; the owner keeps the jail path, the confinement mechanism, the resolved argv and, on a real launch, the canary's result and a sessionId for claude --resume — the evidence that the run was confined. Even here the prompt text is masked to «prompt», so the audit records that a run happened and how it was boxed, without persisting the instruction verbatim. That split — thin wire, complete audit — is what lets you expose execution to a stranger's agent without exposing your machine to it.
Across machines — two paths
Everything above happens on one machine. To let an agent on another machine call claudecode.run, you need reachability, and Plexus gives you two shapes for it. The trust model is identical in both; only where the pend fires and where the sandbox runs differ.
Single machine over a tunnel — publicHostname
Machine A is the machine the agent connects to. You publish A's gateway under a hostname (PLEXUS_PUBLIC_HOSTNAME), and the remote agent enrolls and calls over that longer wire. The switch adds reachability only — the trust model doesn't move: the pend fires on A, the sandboxed run happens on A, the audit lives on A. The home-gateway example is the verified recipe for this shape (a real Cloudflare named tunnel, install → enroll → standing read → pending write → approve → revoke-fails-closed). It demonstrates the pend on workspace.write; claudecode.run rides the exact same path, with the execute-per-use ceiling on top.
Over a tunnel, call the coding capabilities with async: true
The trust model doesn't move, but the wire now has a request-duration cap. A synchronous claudecode.run / codex.run whose work outlives it is answered by the edge (Cloudflare returns 524 at ~100 s) while the gateway runs the task to completion and audits it — the result lost, and a retry starting a second real, credit-burning run. Both entries are marked longRunning: send async: true, take the run handle, and collect from GET /invoke/status?runId=…. See the async invoke channel.
Many machines — the federated mesh
When the coding agent lives on a different machine from the orchestrator, the capability is mounted across a mesh. The cap sits on a proxy machine and mounts onto a parent primary; the agent talks to the parent. Now the two halves separate cleanly: the pend fires in the parent's admin, and the sandboxed run executes on the proxy — the machine that actually owns the Claude Code. Each host keeps its own audit of what it ran.
The mesh-security-audit/cloud example verifies this shape end to end — but with codex.run, not claudecode.run: a cloud agent reaches a Mac workload's Codex over the mesh, sandbox-jailed, pending each call, per-host audit, revoke fails closed.
Honest status
claudecode.run's cross-machine path is structurally identical to codex.run's — same enrollment, same per-use pend, same wire/audit split, same mesh forwarding. The codex.run version is the one verified end-to-end in mesh-security-audit. claudecode.run rides that same path, but its own tests are local record-mode unit tests — there is no separate cross-machine end-to-end run for the Claude Code capability specifically. Treat the mesh path for claudecode.run as "the same mechanism codex proved," not as independently e2e-verified.
Real launch — record to real
Record mode is the default because it proves the whole trust chain without spending a token. When you actually want the worker to do the coding, the owner opts in explicitly:
- In the console: What I expose → Claude Code → Real launch, or
- set
PLEXUS_CC_HEADLESS_LAUNCH=1on the gateway.
With real launch on, the same approved call first runs a canary under Plexus's kernel jail to prove the jail holds, then spawns a headless Claude Code inside it. The response carries a real launched: true, isolation.enforced: true, output, and exitCode instead of the record-mode reason. If the canary fails, the call fails with the reason and Claude Code never starts. This really runs Claude Code and really burns model credit — it is an owner decision, off by default, and every run still rides the same grant gate (per-use unless you opted this execute into standing at connect).
Execution policy — Jail or Host access
Real launch decides whether the tool runs. The execution policy decides what it can reach when it does. Claude Code and Codex each have one, next to Real launch:
- Jail (the default). Plexus runs the tool inside its own kernel sandbox (
sandbox-execon macOS,bwrapon Linux). The authorized directory is the only place it reads and writes, and its temp files live there too. The network stays open for the model. The tool's own login and configuration are readable and stay as they are (settings, hooks, plugins are read-only). The run writes its own session, soclaude --resumeandcodex exec resumework, and it cannot read your other sessions: Claude Code's transcripts, prompt history, pastes, file snapshots and auto-memory, and Codex's rollouts, history, shell snapshots and sqlite stores are out of its reach (on Linux, Codex's own sqlite stores remain readable; see Known limitations). The tool's own sandbox is turned off inside the jail, because two nested sandboxes break its shell and the kernel jail is the boundary. The canary above runs before every real launch. - Host access. The tool runs exactly as if you had started it in a terminal: your user account, all your files, credentials and network, no Plexus sandbox, no canary. That includes
~/.plexus, so a run under Host access could read your connection-key. Turning it on asks you to confirm, and while it is on the source row carries a HOST ACCESS badge.
Switch it in What I expose → Claude Code → Execution policy, or set PLEXUS_CC_EXEC_POLICY=host (PLEXUS_CODEX_EXEC_POLICY for Codex) on the gateway; the console setting wins. Agents can't change it. Every change is audited, takes effect on the next call, and each run's audit records the policy it used. The agent sees it too:
"isolation": {
  "policy": "host",
  "scope": { "files": "host-user", "temp": "host-user", "network": "open", "toolState": "host-user" },
  "enforced": false
}
Where this goes
Multiple workers, one machine — a roadmap. The obvious next step is to expose an Opus entry point and a Sonnet entry point as distinct capabilities, so a caller picks the worker by capability id and you gate each independently. This does not exist yet. Today there is no claudecode kind adapter, and claudecode.run takes no model parameter — its argv is claude -p <prompt> plus CC's permission-bypass flags, still with no --model. Getting there needs (a) a claudecode kind adapter (analogous to the workspace-dir one) and (b) a model parameter threaded through the launcher/entries so it can inject claude --model. Until then, one entry point per machine.
A pool for a fleet. The same per-use-approved pattern, fronted by an always-on neutral gateway with many workers behind it, is the team-scale direction — a resource pool an orchestrator draws from. That's the enterprise shape the federated mesh is built toward; see the mesh-security-audit/cloud example for how the parent-primary + dial-out-proxy machinery already carries it.
The mechanics under all of this are the trust loop you already know — enroll, per-use approval, audit, revoke. Only the capability changes: from reading a file to running a coding agent, which is why the gate never stops asking. See also Connect an agent and the security model for the execute-defaults-to-once rule (owner opt-in required to lift it) in full.